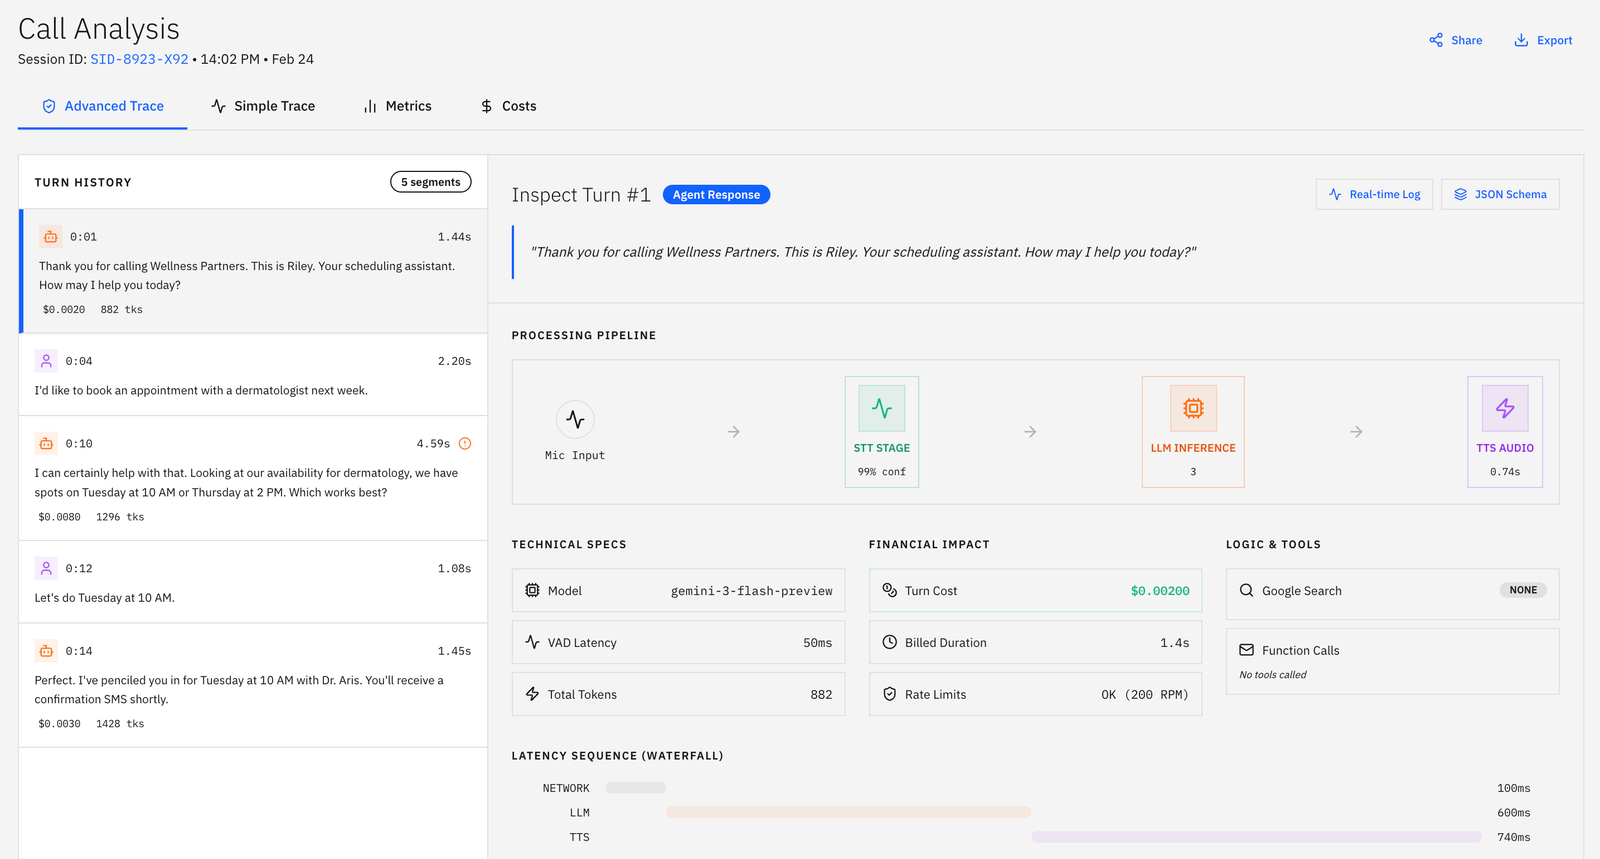
Turn-by-turn traces
Inspect any turn down to the model used, tokens spent, tools called, and the latency contributed by each stage.
Simulate conversations, score every call, and trace latency turn by turn. One platform from staging to production.
Point your provider at Hevo and calls start flowing in. No changes to your agent code.
Sync production calls, recordings, and transcripts.
Import calls with word-level transcript timing.
Connect through a webhook. Ask us to enable it.
Your agent took an action on a live phone call with a real customer. By the time a complaint reaches you, the call is over and the context is gone.
Text users retry. Phone callers hang up, and you never learn why.
Speech recognition, model, and speech synthesis each add delay to every single turn.
Reading a transcript tells you what was said, not how it sounded or where it stalled.
Catch regressions in staging, grade what ships, and keep watching once real callers arrive.
Drive scripted personas through your agent and replay the same scenario after every prompt change.
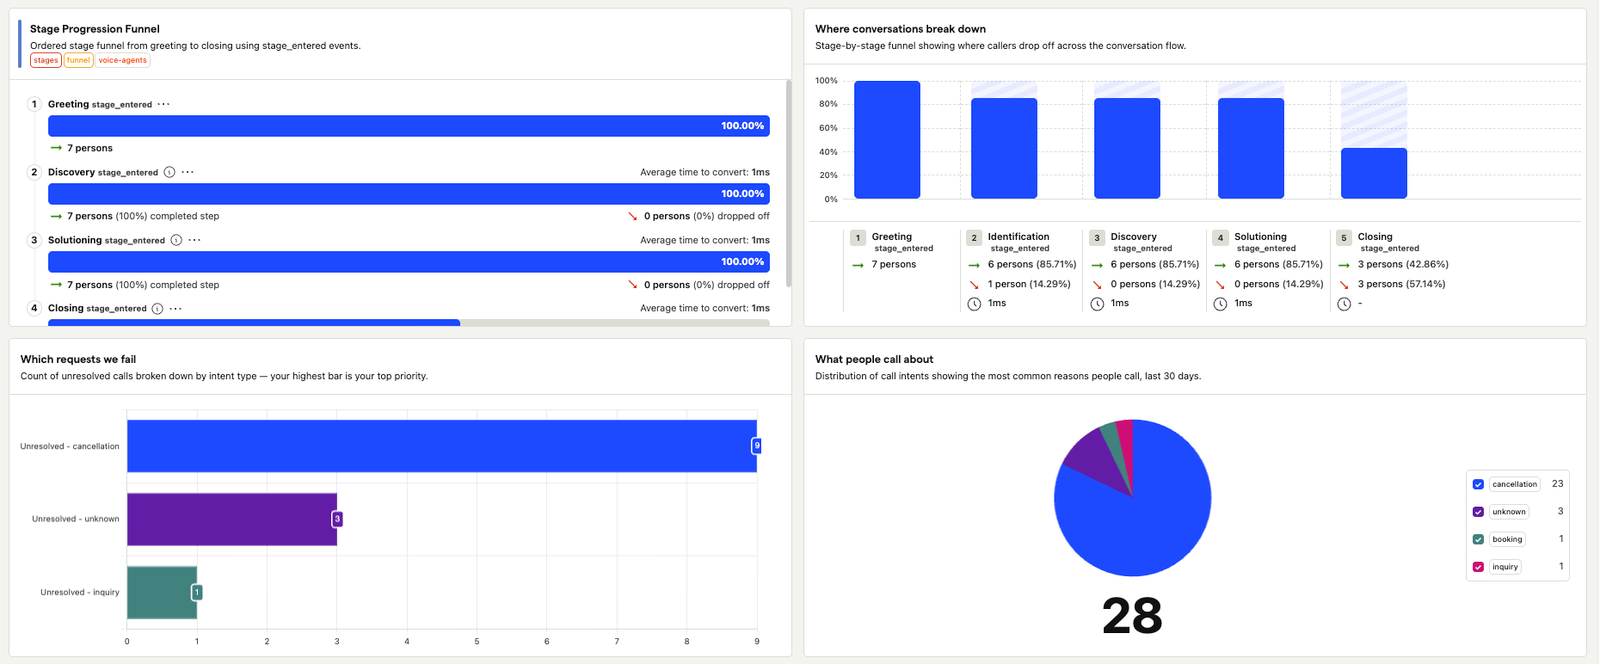
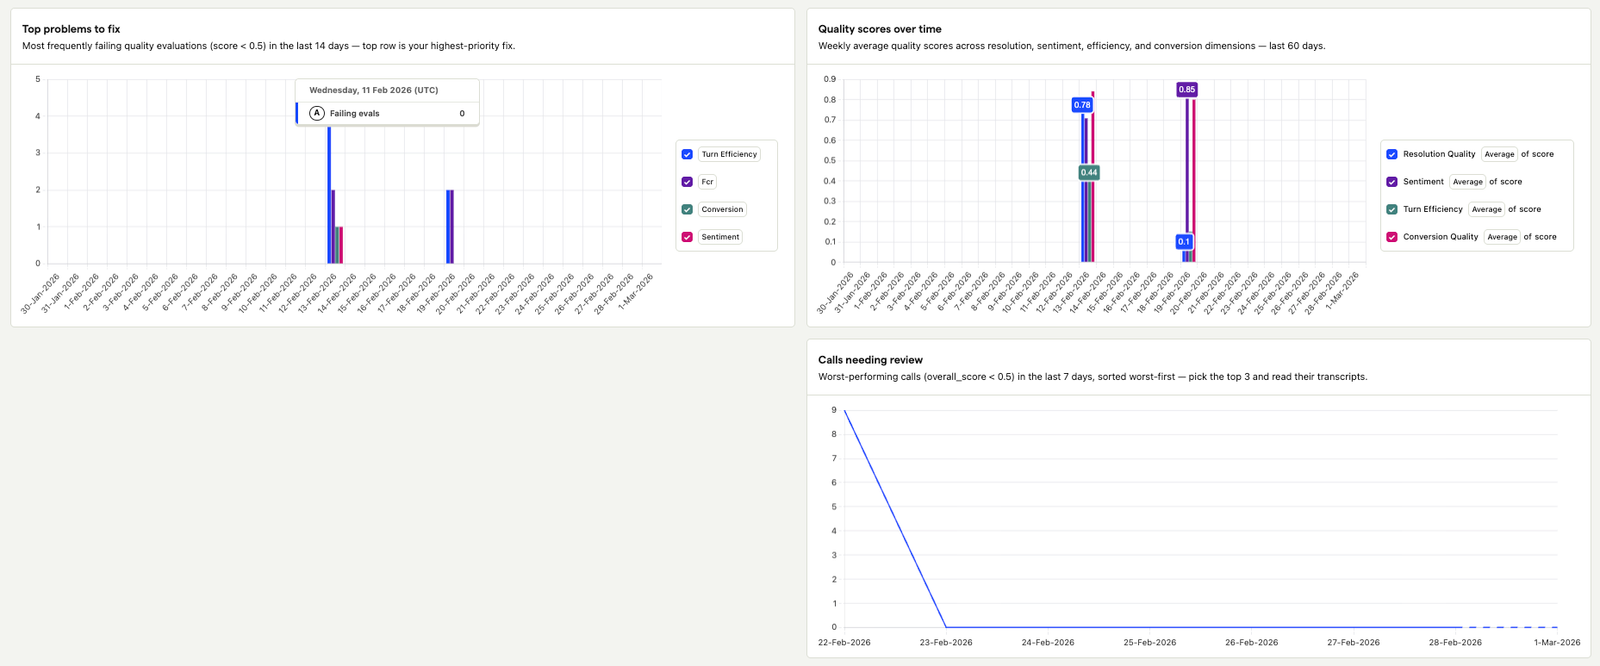
Every call is graded on resolution, sentiment, turn efficiency, and conversion, so you can rank the worst calls first.
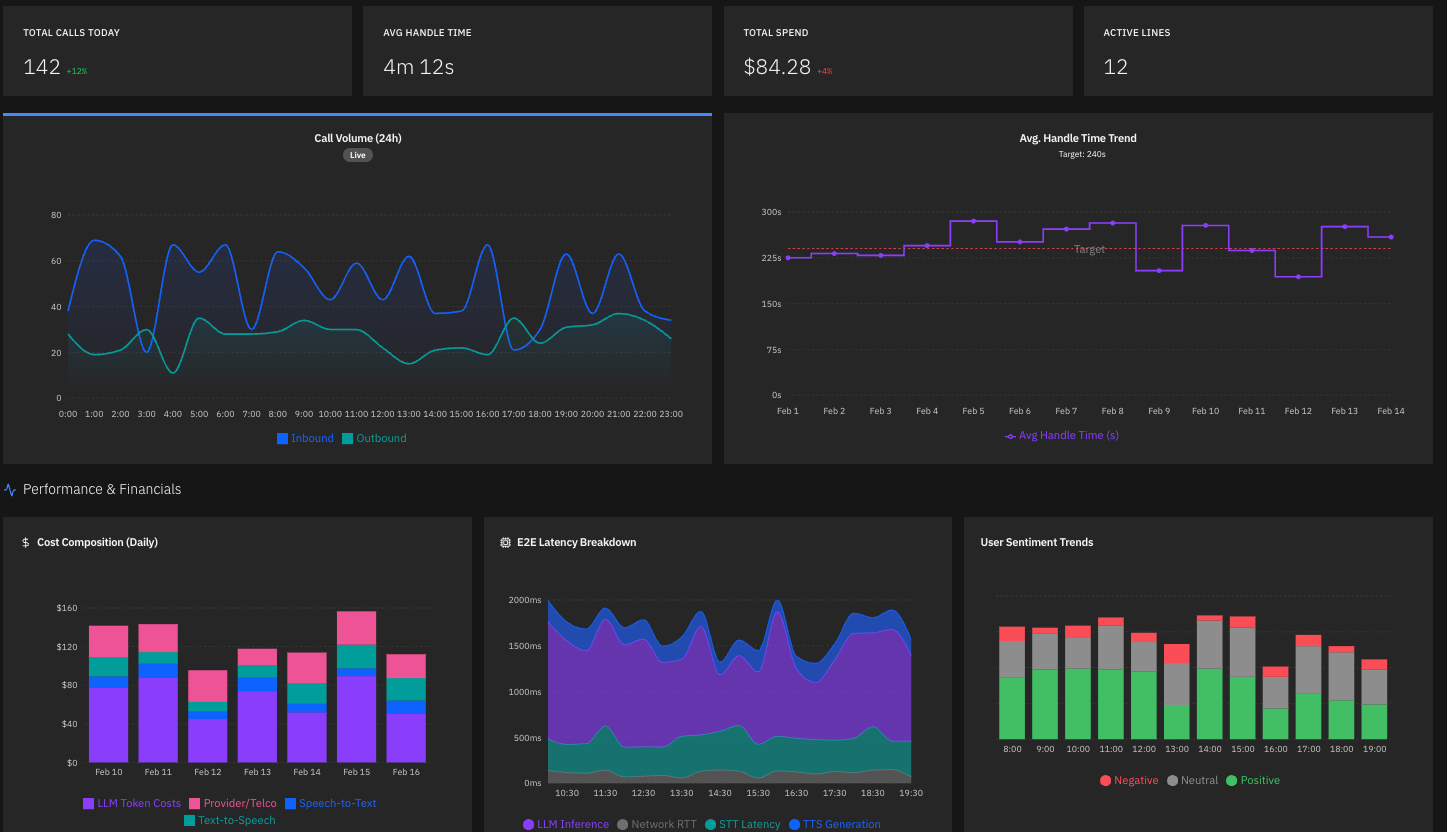
Call volume, handle time, cost composition, and latency breakdown across speech recognition, model, and synthesis.
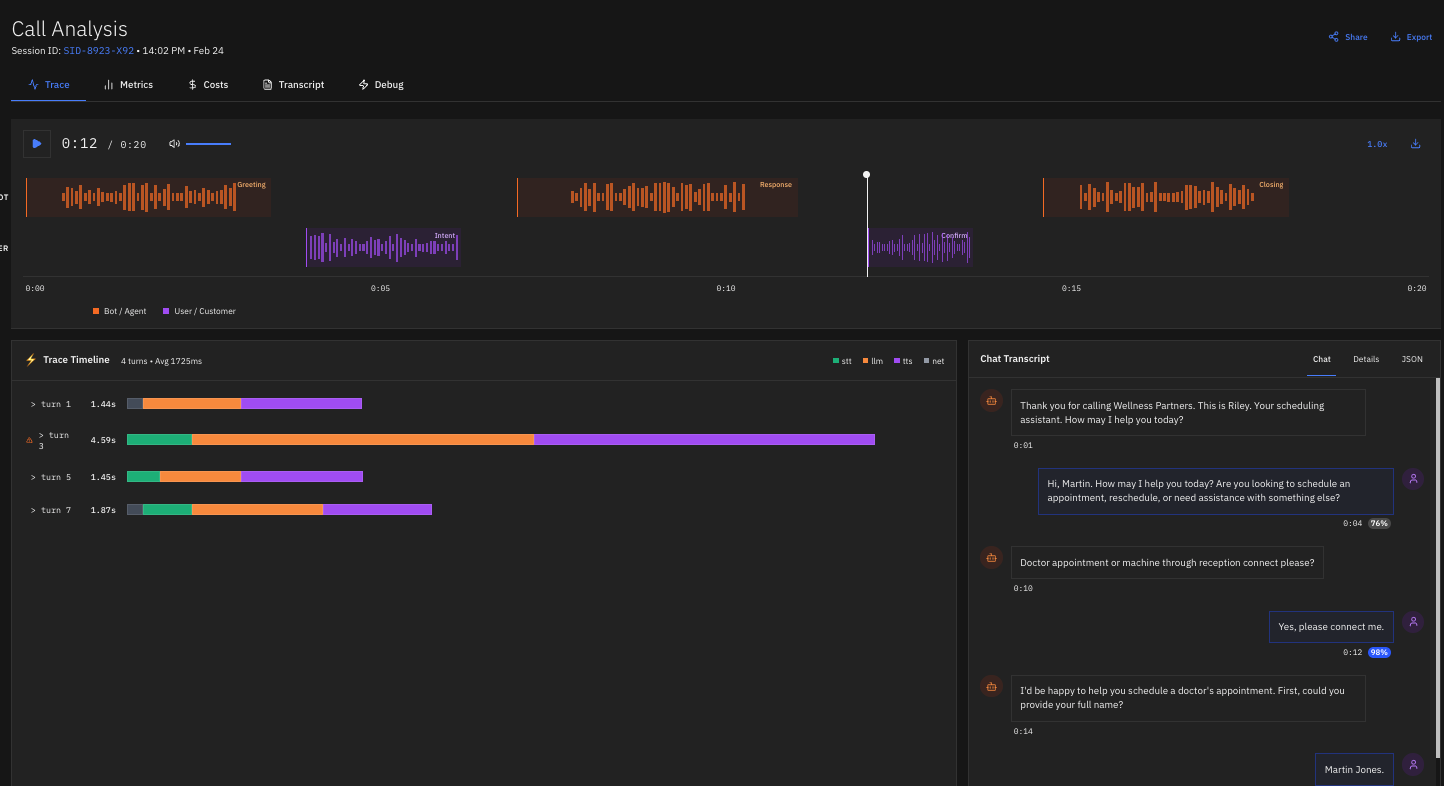
Open any conversation and see exactly what the agent heard, decided, said, and spent.
Inspect any turn down to the model used, tokens spent, tools called, and the latency contributed by each stage.
Spend is split across the model, speech recognition, speech synthesis, and telephony, for every single call.
Scrub the recording and the transcript follows. Hear the pause your users complained about instead of guessing at it from logs.
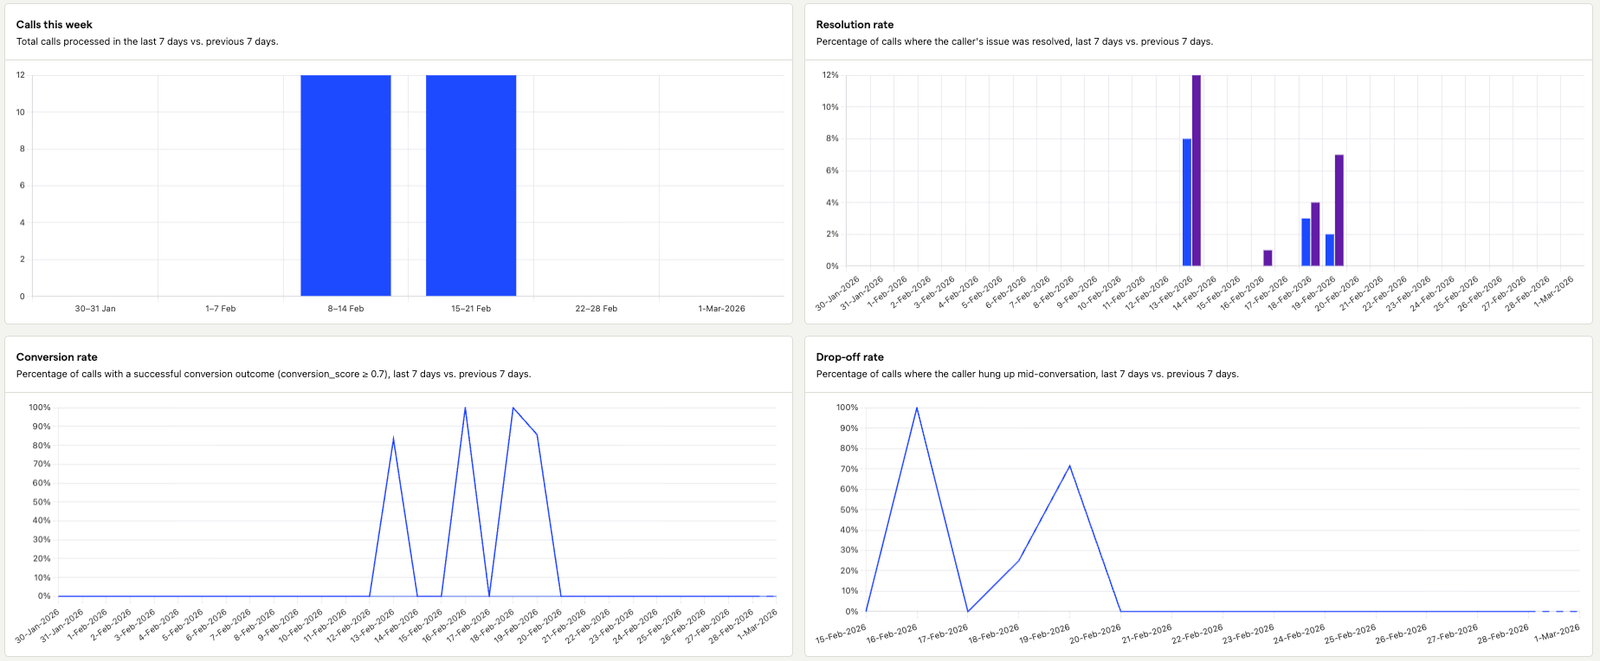
Track resolution, conversion, and drop-off week over week so prompt changes show up as numbers, not opinions.
No SDK to install and no changes to your agent logic.
Add your provider API key in the dashboard and point its webhook at your workspace endpoint.
Recordings, transcripts, traces, and cost land in your workspace as each call ends.
Scores run automatically. Failures and degraded metrics raise a notification.
# Point your provider webhook at your workspace
curl -X PATCH https://api.vapi.ai/assistant/$ASSISTANT_ID \
  -H "Authorization: Bearer $VAPI_API_KEY" \
  -H "Content-Type: application/json" \
  -d '{
    "serverUrl": "https://app.hevo.dev/api/webhooks/vapi",
    "serverMessages": ["end-of-call-report", "status-update"]
}'Call recordings are sensitive. Here is what is in place today, and what is not yet.
Provider and model API keys are encrypted with AES-256-GCM before they are stored.
Run evaluations against your own model accounts so inference stays on your billing and your terms.
Calls, agents, and evaluation runs are scoped to a workspace, with roles controlling access.
We do not train models on your calls, transcripts, or recordings.
SSO and SAML, SOC 2 Type II, Configurable data retention. If one of these blocks a rollout for your team, get in touch and we will share timelines.
Bring a provider key and a handful of recent calls. We will walk through what the traces and scores show.